Fast chat · source-groundedQwen + Rhys sources
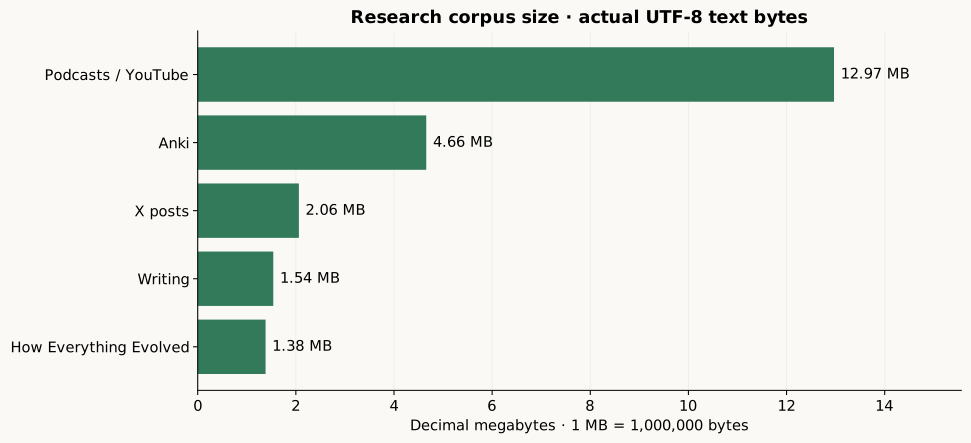
An existing Qwen3-30B-A3B model receives relevant excerpts from Rhys’s writing, How Everything Evolved, podcasts, X and curated notes with your question.
The excerpts are looked up at inference time. This mode does not change Qwen’s weights. In side-by-side comparison, the other Qwen answer receives no Rhys corpus and keeps its own conversation.
Open the default chat ↗
Saved adaptation · trained weightsQwen3.5-4B + CPT/SFT
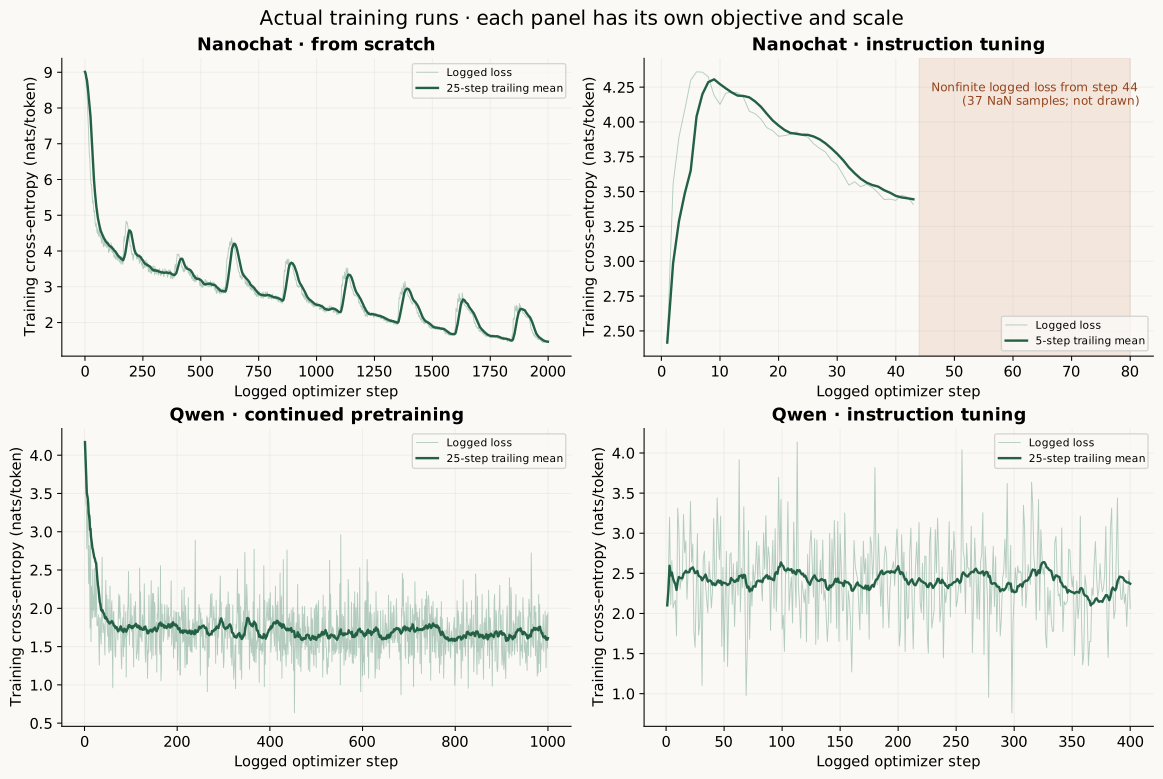
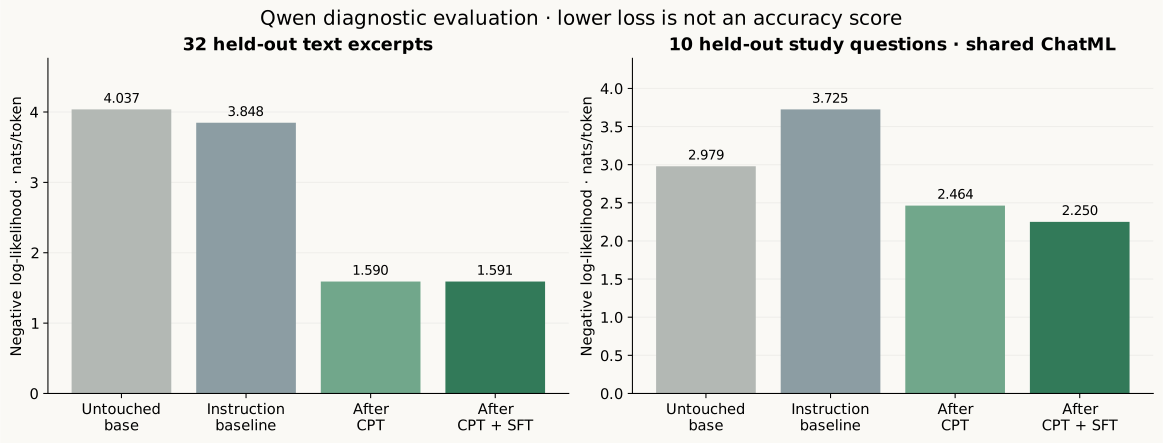
Start from existing Qwen3.5-4B base weights. Continued pretraining (CPT) on Rhys’s corpus ran for 1,000 updates, then supervised fine-tuning (SFT) ran for 400 updates.
A saved LoRA adapter contains the learned changes. The checkpoint comparison runs that adaptation beside the same 4B base with its adapter disabled. It receives no retrieved corpus excerpts.
Choose “Trained 4B vs Qwen 4B base” ↗
Pure nanochat Rhys · from scratchA tiny model, built from zero
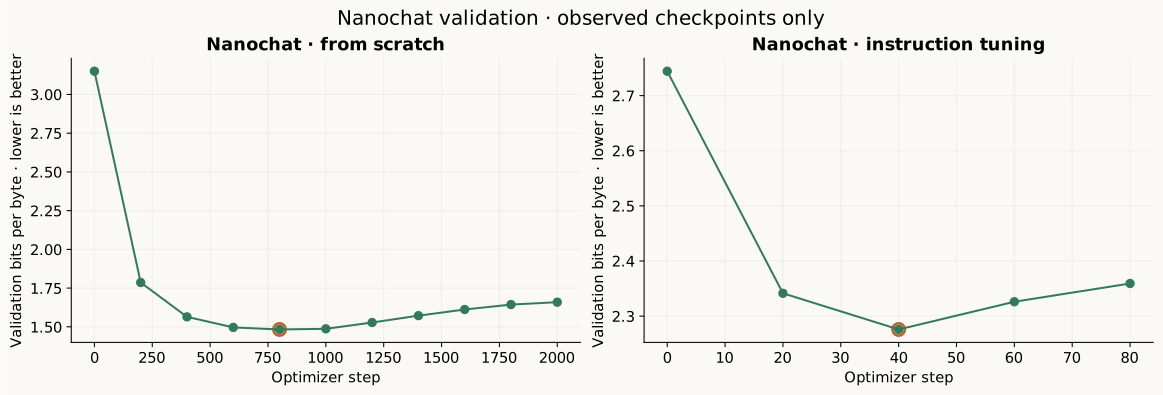
nanochat began with random weights: 4 layers, an 8,192-token vocabulary and a 512-token sequence length. It ran 2,000 pretraining updates, then a short 80-update SFT run.
This mode uses only that saved scratch checkpoint. No Qwen, retrieved passages or hidden fallback answer for it. Every valid reply shows its checkpoint run, weights hash and token counts.
It is a tiny learning experiment. Current samples are often incoherent; SFT logged NaNs from update 44. Finishing a training run is not evidence that it became a useful chatbot.
Choose “Pure nanochat Rhys” when available ↗