What did the model learn?
Compare the saved Rhys Qwen adapter with the same Qwen base model on released Anki question/reference pairs. Inspect automatic measurements, read actual answers, and add your own local review.
A reference card is not an independently verified fact. Lower loss, exact match and token overlap measure different things; none establishes correctness or fidelity to Rhys’s beliefs. A card’s frozen training split is membership metadata, not proof that an optimizer consumed that exact example.
Adapter versus base.
Evaluation in progress. Measured results will appear when the report is available.
| Frozen SFT split | Cards | Target tokens | Rhys NLL | Qwen base NLL | Cards: Rhys lower NLL | Cards: base lower NLL | Ties |
|---|
NLL measures how well the model predicts the reference answer’s tokens. The colored bars compare the reported NLL values within each split; card counts with lower loss are not accuracy scores. Training-split results are not held-out generalization results. This benchmark supplies text only: image-bearing cards may lack necessary context. Generated-answer samples exclude those cards.
Generated-answer overlap
| Model | Normalized exact match | Token overlap F1 |
|---|
Dataset manifest · Model and training explanation · Training loss chart · Earlier Qwen held-out chart
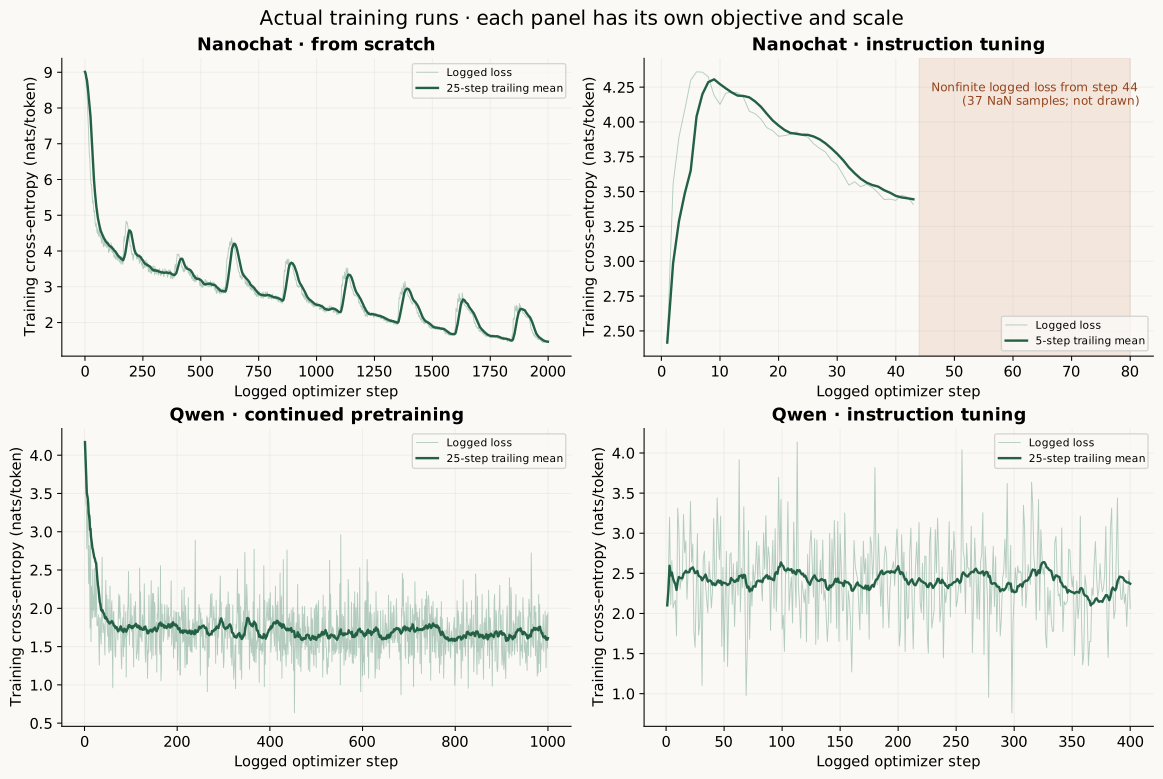
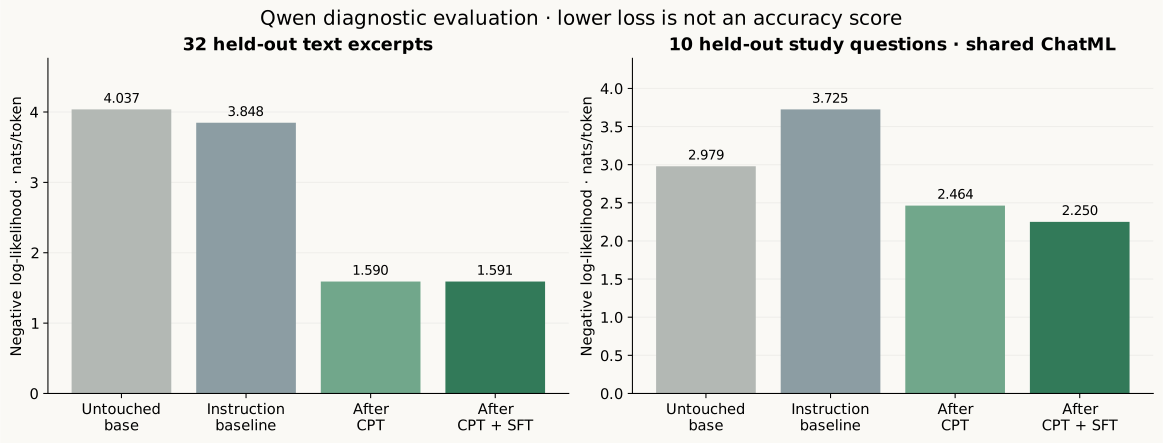
Look at actual answers.
Each pair uses the saved adapter and the same base model without that adapter. These are recorded model outputs, with no retrieval fallback. Reveal the reference card when useful. Human reviewer labels below are your judgments, separate from automatic metrics.
Load public answer samples to inspect and review them.
Your local reviews
No reviews loaded.
Labels and optional corrections are saved only in this browser, capped at 200 KiB. Full public questions and model answers are joined into your JSONL export; they are not duplicated in local review storage. Nothing is sent, published or used for training automatically. Export is for later review and curation.
Find a question.
The full QA and score downloads happen only when you choose Load all QA. After loading, search and filtering stay in the browser. A maximum of 30 cards is rendered per page.
Full QA has not been downloaded.
| Question & reference | Frozen SFT split | Rhys NLL | Qwen base NLL | Target / full tokens | Truncated? |
|---|
Truncation means the scored target used fewer tokens than the full reference. Unscored cards show a dash rather than an invented loss. Comparisons here evaluate the reported target span, not an independently verified factual answer.
Loading the manifest and measured summary…